By Raj Brar, Founder of Argus AI Labs
I learned the value of domain-specific data long before the term existed.
In the 1990s, I ran automotive diagnostic centres as vehicles were becoming computer systems on wheels. A manufacturer could provide the service manual, fault codes, wiring diagrams, and operating specifications. Every capable shop had access to much of the same general information.
What separated one diagnostic operation from another was the knowledge created through the work.
We learned which fault codes appeared together, which symptoms pointed away from the obvious component, which repairs failed under load, and which sequence of tests exposed the real problem. The equipment generated data. The technicians added judgment. The outcome told us whether that judgment was right.
That accumulated operating history became more valuable than the manual because it reflected problems we had actually seen and decisions we had already tested.
I see the same distinction in enterprise AI today.
Large language models are like the manufacturer manual at an extraordinary scale. They know an enormous amount about the public world. They do not arrive knowing your internal terminology, decision rights, operating history, exceptions, evidence standards, or current source of truth.
A domain-specific dataset gives an AI system a governed representation of that knowledge. It captures what the organization has learned through operating—not only what its documents say.
The model matters. The dataset determines whether the model can do useful work inside your organization.
What is a domain-specific dataset?
A domain-specific dataset is a curated body of information built for a defined field, operating context, or decision.
It may include documents and database records, but a useful dataset is more than a collection of files. It can also encode:
- the meaning of company-specific terms;
- relationships among customers, products, policies, assets, and events;
- which sources carry authority;
- when information became valid and when it expired;
- known exceptions and edge cases;
- expert judgments and reviewed outcomes;
- permissions governing who and what may use the information; and
- test cases that show whether an AI system performs acceptably.
The word dataset sometimes makes executives picture a spreadsheet prepared for a data science team. That definition is too narrow. For enterprise AI, the dataset is the usable expression of what the organization knows about a particular job.
Raw information is an input. A domain-specific dataset is an engineered asset.
Why a general model cannot know your business
An organization often has more internal information than it can effectively use. Contracts sit in one repository. Procedures live in another. Important exceptions survive in email. Definitions vary among departments. Experienced people carry context that was never written down.
None of this becomes reliable AI knowledge merely because the company has stored it somewhere.
Research into enterprise data integration illustrates the problem. In Mind the Data Gap, researchers evaluated language-model methods against a benchmark derived from real enterprise data. They found that performance on the enterprise benchmark was materially worse than on comparable public-data benchmarks for the task they studied. Their conclusion was appropriately specific: testing on public data can paint an overly optimistic picture of performance on private organizational data.
Microsoft researchers reported a related limitation in industrial question answering. General models performed well on open-domain tasks but lacked some of the domain knowledge required for the technical scenarios in their benchmark.
These findings do not mean language models are unsuitable for enterprise use. They show why a strong model is only one layer of the system. The model’s broad capability must be connected to knowledge prepared for the organization’s actual vocabulary, conditions, and decisions.
This is also why buying a larger model does not necessarily fix a weak enterprise implementation. More general capability cannot resolve a conflict between two internal policies when the system has no way to know which policy is authoritative or current.
Your files are not yet a dataset
Many AI programs start by indexing a document repository. That can be useful, but it is the beginning of data preparation, not the end.
Consider a service manual that was superseded six months ago. It may be well written, highly relevant to a search query, and wrong for the present situation. A retrieval system can find it perfectly and still produce the wrong answer.
The same problem appears when:
- duplicate records disagree;
- internal labels mean different things across business units;
- a policy applies only in one jurisdiction;
- an expert note is useful but not authoritative;
- a customer record contains restricted information; or
- the correct answer depends on the sequence of earlier events.
AI data curation is the work of resolving those conditions. It turns accumulated information into evidence that a system can use within defined boundaries.
For leaders, the distinction matters. A document migration project asks whether content was moved and indexed. A domain dataset program asks whether the organization has represented enough meaning, authority, time, and context to support a specific decision.
The seven properties of a valuable domain dataset
The best domain-specific datasets are not necessarily the largest. They are fit for a clearly defined purpose and managed as living operational assets.
A decision boundary
Start with the job the system must support. “Use AI in customer service” is too broad. “Identify the governing warranty policy for a claim, cite the current source, and escalate ambiguous cases” creates a boundary that data owners, domain experts, and evaluators can examine.
Without a decision boundary, teams collect information indefinitely and cannot say whether the resulting dataset is complete enough.
Deliberate source admission
Every available source does not deserve equal status. Teams need rules for what enters the dataset, what remains reference material, and what is excluded.
Useful admission questions include:
- Who created the source?
- For what operational purpose?
- Is it still in force?
- Does the organization have permission to use it this way?
- What other source can override it?
This is where proprietary datasets for AI begin to develop practical value: through selection and control, not volume alone.
Shared meaning and relationships
A model needs more than text similarity when the answer depends on how business concepts relate.
A “customer” may be a buyer in one system, an account group in another, and a legal counterparty in a third. A good domain dataset reconciles or explicitly maps those meanings. It can represent relationships among entities, rules, events, and outcomes so the AI system does not treat every passage as an isolated fragment.
This semantic layer may take the form of a taxonomy, ontology, knowledge graph, metadata model, or a simpler controlled vocabulary. The form should follow the decision being supported.
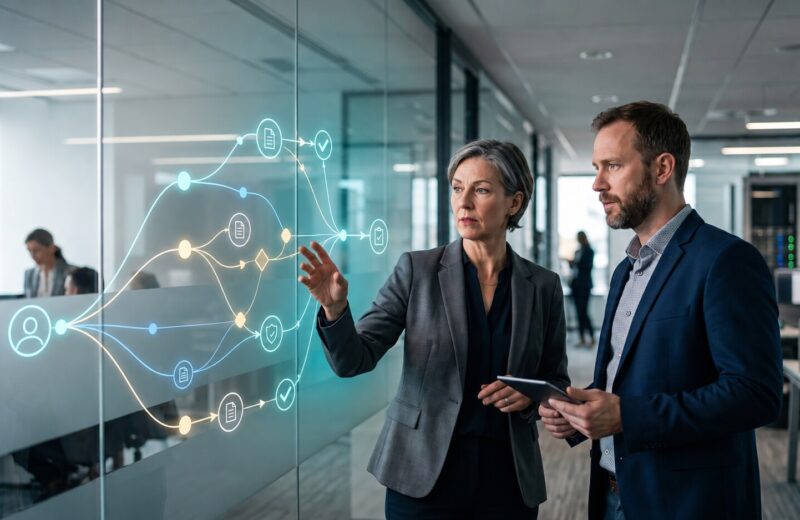
For consequential work, the operational mechanics matter. A property graph can represent a policy, customer, jurisdiction, product, exception, and decision as separate nodes. Typed relationships can state that one rule applies to a product, supersedes an earlier rule, requires an approval, or was supported by a particular source. Valid-from and valid-to fields can constrain when those relationships are true. Provenance can connect every claim to the evidence and transformation that produced it.
That structure allows a hybrid system to use vector retrieval for linguistic similarity and graph traversal for explicit business relationships. The vector layer may find a relevant passage. The graph layer can test whether the passage is current, authoritative, connected to the right entity, and applicable to the decision. Neither layer replaces the other.
Provenance and time
Every important fact should carry enough context to answer: Where did this come from? Who changed it? When was it valid? What transformation was applied?
NIST’s AI Risk Management Framework and supporting playbook emphasize data provenance as part of transparency and accountability. The playbook specifically points organizations toward documenting sources, origins, transformations, labels, dependencies, constraints, and metadata.
Provenance is not paperwork added after a system is built. It is how operators investigate a questionable answer, how reviewers distinguish evidence from inference, and how teams update knowledge without losing the history of a decision.
Domain judgment
Some of the highest-value information in a business is not a settled fact. It is judgment: why an experienced operator chose one path, which exception mattered, what evidence was insufficient, or when the right action was to escalate.
Capturing judgment requires participation from the people who understand the work. Data teams can organize the material, but they cannot infer every operational distinction from database fields.
The goal is not to extract everything an expert knows. It is to preserve the decisions, examples, and distinctions that repeatedly affect the defined task.
Evaluation cases
A dataset should help the system answer questions. It should also help the organization test whether those answers are good enough.
Build a set of representative cases, difficult cases, known failure modes, and cases that should trigger human review. Record the expected evidence and acceptable outcome. Update the evaluation set when production use reveals a new edge case.
This creates a feedback loop between operations and system quality. Without it, leaders receive demonstrations and anecdotes instead of measurements tied to the work.
Permission and stewardship
Domain data often contains sensitive commercial, personal, legal, or operational information. Access cannot be an afterthought.
The dataset needs an accountable owner, defined users, permitted purposes, retention rules, and a process for correction. Those controls should carry through to retrieval, model use, logs, and human review.
An AI system should not gain broader access merely because its interface makes access convenient.
We learned this by building the wrong evidence path first
The distinction became concrete while my team and I were building NEXOSAT, a governed legal intelligence system for Mexican federal tax law.
Our early retrieval work could find authentic provisions containing the right legal vocabulary. On a conventional relevance test, those results looked strong. But a relevant provision could be wrong for the date, altered by a later rule, limited by an exception, or dependent on an authority whose language looked nothing like the question.
The model was not the first failure. The evidence path was.
We had treated legal sources too much like passages and not enough like a system. We redesigned the architecture around authority, provenance, temporal validity, applicability, and explicit relationships among statutes, annual rules, administrative material, and judicial interpretation.
Before, retrieval could answer: Which text resembles the question?
After the redesign, the system could investigate a harder sequence: Which authorities are connected to this issue, which version was valid, what relationship does each authority have to the others, what evidence supports the path, and where must the system refuse because the governing chain is incomplete?
That is a real before-and-after from our internal R&D. It is not a claim of client ROI, and I will not manufacture a percentage to make the story sound more commercial. The measurable change was architectural: we moved from retrieving related language to reconstructing an inspectable evidence path.
In a consequential domain, that is the difference between an answer that sounds informed and a system whose reasoning can be challenged.
RAG or fine-tuning is the second question
Teams often begin with an architecture debate: Should we use retrieval-augmented generation or fine-tune a model?
That is an important design choice, but it comes after the dataset question.
RAG can bring current, attributable information into a model’s context. Its usefulness depends on what was indexed, how content was segmented and described, whether retrieval recognizes the right relationships, and whether the correct source rises above plausible but obsolete alternatives.
Fine-tuning can shape model behavior and improve performance on well-defined domain patterns. It also requires prepared examples, quality controls, and a method for testing what the tuned model learned or distorted.
Practical research on enterprise fine-tuning makes the same dependency visible: fine-tuning seeks to incorporate proprietary domain knowledge, while retrieval systems are constrained by the quality of their data and retrieval layer.
In other words, both approaches consume a data asset. Neither turns disorganized information into reliable knowledge by itself.
A mature architecture may use the same governed dataset in several ways: retrieval for current evidence, fine-tuning for repeated patterns, evaluation for quality control, and analytics for operational learning. That reuse is one reason the dataset can outlast an individual model choice.
The cost is not in collecting data. It is in maintaining judgment.
Building a living domain dataset takes time from the people who understand the work. They must resolve contradictions, define terms, review edge cases, validate relationships, and decide which corrections deserve to become institutional knowledge.
That is the real curation bottleneck.
The wrong response is to begin by capturing everything. The cost becomes open-ended, experts lose patience, and the organization creates a large repository without proving that it improves a decision.
I would begin with the smallest consequential loop:
- one recurring decision;
- the sources and expert judgments required to make it;
- the expensive exceptions and failure cases;
- the evidence a reviewer must see;
- the conditions requiring escalation; and
- the outcome that reveals whether the decision worked.
Automation can reduce the mechanical work. Models can propose entities, relationships, labels, duplicates, and possible contradictions. They can prepare material for review and identify records affected by a source change. They should not silently promote those proposals into governed truth.
The operating model should make stewardship part of the workflow rather than a separate cleanup project. Review the changes that affect consequential decisions. Sample lower-risk material. Track expert-review demand, unresolved conflicts, stale sources, and the cost per accepted case. Retire parts of the dataset that no longer support a real use.
A domain dataset earns continued investment when it reduces repeated investigation, improves decision quality, preserves scarce expertise, or creates a reusable capability across workflows. If the organization cannot connect the curation burden to one of those outcomes, it is maintaining data without a business case.
Where the value compounds
Models and infrastructure will continue to change. A domain-specific dataset can become more useful with each reviewed decision.
A corrected answer can reveal a missing exception. An escalation can expose an ambiguous policy. A new regulation can trigger a version change. A domain expert can identify a relationship the retrieval layer was missing. Each event can improve the data, the evaluations, and the system’s operating boundaries.
This is a compounding process only when the feedback is captured. If corrections remain in chat transcripts or in the head of the person who caught the mistake, the organization repeats the same learning cost.
The durable asset is the organized record of what the business knows, how it knows it, when that knowledge applies, and how well a system uses it.
What I have learned building governed intelligence systems
Across our internal legal and land-intelligence R&D at Argus AI Labs, the hardest problems have rarely been solved by adding more documents to a prompt. The work becomes more reliable when the system can represent authority, provenance, temporal validity, permissions, and relationships explicitly—and when uncertain outputs return to human review.
That is a design observation, not a claim that every organization needs the same architecture. A narrow workflow may need a carefully governed table and a strong evaluation set. A complex investigation may require an ontology, multi-hop relationships, source-level permissions, and evidence tracing.
The architecture should be proportional to the decision. A narrow workflow may need a governed table, explicit source rules, and a strong evaluation set. A complex investigation may need an ontology, a property graph, multi-hop traversal, source-level permissions, temporal reasoning, and a complete evidence trace.
My diagnostic instinct remains the same as it was in the automotive business: do not replace the most visible component and assume the system is fixed. Trace the signals. Test the relationships. Preserve what changed. Prove why the result should be trusted.
The domain dataset is where that discipline becomes an organizational asset.
Five questions leaders should ask now
Before approving another model pilot, ask:
- Which recurring decision are we trying to improve? Name the user, the action, and the cost of a wrong answer.
- What knowledge does that decision require? Include sources, relationships, exceptions, history, and expert judgment.
- Who decides what is authoritative and current? Assign stewardship before conflicts appear in production.
- How will we test the system against our real conditions? Build evaluation cases from the work, not solely from public benchmarks.
- How does every correction improve the asset? Create a governed path from human review back into data, tests, and system rules.
These questions move an AI initiative away from a model demonstration and toward an operating capability.
The asset behind the interface
The visible part of enterprise AI is the interface: a chat window, a copilot, a search bar, or an automated workflow.
The durable value sits underneath it.
It is the domain-specific dataset that explains the organization’s language, connects evidence to decisions, preserves provenance, respects permissions, and learns from reviewed outcomes. That asset makes it possible to change models without rebuilding the organization’s knowledge from scratch.
The next generation of models will be more capable and more widely available. Your organization’s operating knowledge will remain specific to you.
The companies that turn that knowledge into governed, reusable datasets will be in a stronger position to convert general AI capability into business value they can actually trust.
Start with one decision your general model cannot make
At Argus AI Labs, we identify the knowledge behind a consequential business decision, map its sources, authority, relationships, temporal conditions, permissions, and failure cases, and determine what architecture is required to make that knowledge usable.
If your AI pilot can retrieve company information but cannot reliably determine what applies, what is current, or why an answer should be trusted, bring us that decision.
About Argus AI Labs
Argus AI Labs builds enterprise intelligence systems around organizational data, verified knowledge, provenance, permissions, human review, and continuous evaluation. Our work begins with what an organization uniquely knows and the decisions that knowledge must support.
Sources
- Moe Kayali et al., “Mind the Data Gap: Bridging LLMs to Enterprise Data Integration,” 2024: https://arxiv.org/html/2412.20331v1
- Fangkai Yang et al., “Empower Large Language Model to Perform Better on Industrial Domain-Specific Question Answering,” 2023: https://arxiv.org/abs/2305.11541
- Mathav Raj J et al., “Fine Tuning LLM for Enterprise: Practical Guidelines and Recommendations,” 2024: https://arxiv.org/abs/2404.10779
- NIST, AI Risk Management Framework Playbook — MEASURE: https://airc.nist.gov/airmf-resources/playbook/measure/
- NIST, Artificial Intelligence Risk Management Framework (AI RMF 1.0): https://nvlpubs.nist.gov/nistpubs/ai/nist.ai.100-1.pdf